
Free Databricks Databricks-Machine-Learning-Professional Practice Test & Real Exam Questions
A Machine Learning Engineer needs to digitize millions of historical documents spanning 200+ years with vastly different handwriting styles, fonts, languages, document conditions, and paper types. To do this, the engineer wants to train thousands of specialized OCR models to extract text. The number of documents vary significantly. They need an efficient approach for this parallel model training task. Which approach suits their needs?
Correct Answer: A
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
What does an Estimator do in Spark ML?
Correct Answer: A
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A data scientist has computed updated rows that contain new feature values for primary keys already stored in the Feature Store table features. The updated feature values are stored in the DataFrame features_df. They want to update the rows in features if the associated primary key is in features_df. If a row's primary key is not in features_df, they want the row to remain unchanged in features. Which code block can they use to perform this task using the Feature Store Client fs?
Correct Answer: D
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A Machine Learning Engineer is tasked with building an automated daily pipeline that updates a customer_features table in Unity Catalog. They have implemented a function, compute_customer_features, that returns a DataFrame with a unique customer_id as the primary key and want to ensure the latest feature values are merged into the table each day. Which code snippet implements this requirement?
Correct Answer: C
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A Machine Learning Engineer needs to develop a custom anomaly detection model that monitors the internal IT infrastructure of their company. The model takes in compute metrics, logs, and user data and generates a binary prediction. The engineer plans to deploy it as a Databricks Model Serving endpoint. In production there will only be one client calling the endpoint once every
15 seconds. Leadership sees the model as an important part of their operational improvement strategy so maintaining consistent, stable, low latency inference is a requirement while minimizing infrastructure costs. The engineer plans to deploy the endpoint via the MLflow Deployment SDK.
Which endpoint config for the MLflow Deployment SDK should the engineer select?
15 seconds. Leadership sees the model as an important part of their operational improvement strategy so maintaining consistent, stable, low latency inference is a requirement while minimizing infrastructure costs. The engineer plans to deploy the endpoint via the MLflow Deployment SDK.
Which endpoint config for the MLflow Deployment SDK should the engineer select?
Correct Answer: B
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A machine learning engineer needs to select a deployment strategy for a new machine learning application. The feature values are not available until the time of delivery, and results are needed exceedingly fast for one record at a time. Which of the following deployment strategies can be used to meet these requirements?
Correct Answer: B
Vote an answer
A data scientist wants to track the runs of their random forest model. The data scientist is changing the number of trees and the maximum depth of the trees in the forest across each run.
They write the following code block:
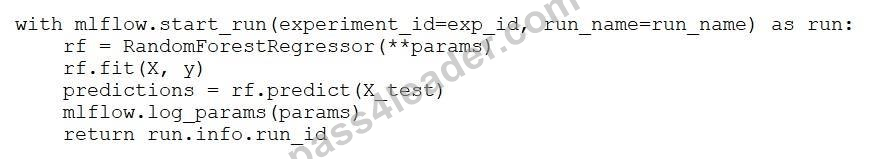
Which Python object type does params need to be an instance of?
They write the following code block:
Which Python object type does params need to be an instance of?
Correct Answer: B
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A Data Scientist at an online gaming company is creating a model to predict player churn. The company currently collects terabytes of player activity logs daily, which are stored in Databricks and processed for daily reporting. The Data Scientist has completed feature engineering and the resulting data is saved as a Delta Table with a size of 500GB. They need to next build the model for the most performant and cost-effective performance for Databricks. Which approach will do this?
Correct Answer: B
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A retail company wants to better forecast their sales of each SKU in every store in order to more accurately distribute their products. To achieve this, a Data Scientist proposes scaling their existing forecasting model to forecast individually for each combination of SKU and Store ID.
They have a cluster with 12 executors available in order to execute this. The current model is written using Pandas and the Prophet library for forecasting, with a Python function that receives a Pandas Data Frame with historic sales data as a parameter to train the forecasting model. For their next iteration, they want to improve the efficiency of this approach while using the least amount of effort and leveraging all available resources. Which approach will do this?
They have a cluster with 12 executors available in order to execute this. The current model is written using Pandas and the Prophet library for forecasting, with a Python function that receives a Pandas Data Frame with historic sales data as a parameter to train the forecasting model. For their next iteration, they want to improve the efficiency of this approach while using the least amount of effort and leveraging all available resources. Which approach will do this?
Correct Answer: D
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A machine learning engineer would like to compute predictions on inference data as it becomes available through the pipeline in microbatches. The predictions should be stored in a table for query later. Which deployment strategy can the engineer use?
Correct Answer: D
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
A Machine Learning Engineer needs to build a time series model. In Databricks, they have created isolated environments in different workspaces for development, staging, and production.
To manage this model, they are planning on using a "deploy code" strategy. They are concerned that the model trained in development will not remain consistent across environments, due to differences in the dependencies installed. What can they do to ensure that the model is trained with the same packages?
To manage this model, they are planning on using a "deploy code" strategy. They are concerned that the model trained in development will not remain consistent across environments, due to differences in the dependencies installed. What can they do to ensure that the model is trained with the same packages?
Correct Answer: A
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
Which of the following describes the purpose of the context parameter in the predict method of Python models for MLflow?
Correct Answer: B
Vote an answer
A Machine Learning Engineer is building an application that requires low latency data lookups in response to a user's question following a RAG based search. They want to ensure their users can receive as recent data as possible for urgent requests, so data should not be more than a few minutes late. The underlying data is a large table that may contain hundreds of gigabytes of data. Which data serving approach will suit their use case?
Correct Answer: D
Vote an answer
Explanation: Only visible for Pass4Leader members. You can sign-up / login (it's free).
